HOME › REVIEWS › AI MODELS

104 reviews. AI Models.

AVG SCORE: 6.8/10

104 of 1538 reviews AI Models × Clear all
01
Llama 4 Maverick L
Llama 4 Maverick
AI Models 53 sources · <60%

"Available chatter tracks Cerebras speed claims and 'did it cheat?' benchmark drama — almost no hands-on reports of th…"

4.0
/10
2 NOV
02
Gemma 3 G
Gemma 3
AI Models 103 sources · 90%+

"Open-weights LLM family (270M-27B) earns praise for local quality and multilingual output; users flag safety refusals…"

7.0
/10
30 OCT
03
Gemini 4 Carbon G
Gemini 4 Carbon
AI Models 38 sources · 60-89%

"Google's frontier model tops the AA Index v5.0, but users hit rollout chaos, quota burn and plan confusion; sibling A…"

6.5
/10
29 OCT
04
Gemini 2.5 Flash G
Gemini 2.5 Flash
AI Models 76 sources · 90%+

"Hands-on users rank its multi-image editing near best-in-class but report reliability misses; videos praise plan valu…"

7.2
/10
26 OCT
05
Kimi K3.1 Pro K
Kimi K3.1 Pro
AI Models 17 sources · <60%

"Moonshot's open-weight LLM wins on price and openness, but users say it trails Opus 5/5.5 and ships with deliberately…"

7.0
/10
24 OCT
06
Gemini 2.5 Pro G
Gemini 2.5 Pro
AI Models 106 sources · 90%+

"Google's flagship LLM earns 'most capable model' praise from a few developers, but direct user reports are thin and v…"

7.5
/10
23 OCT
07
DeepSeek V4.1 Flash 1017 D
DeepSeek V4.1 Flash 1017
AI Models 90 sources · 60-89%

"Open-weight 536B+16B MoE praised as a cheap, self-hostable coding workhorse; trails closed frontier models on intelli…"

7.0
/10
21 OCT
08
MiniMax M3.1 Flash M
MiniMax M3.1 Flash
AI Models 49 sources · <60%

"Free, fast-on-paper coding LLM, but users report post-launch quality drops, provider-dependent speed, and rivals like…"

6.0
/10
21 OCT
09
Gemini 4 Argon G
Gemini 4 Argon
AI Models 124 sources · 90%+

"Google's frontier model impresses users and video audiences on capability, but draws anger over usage limits, CLI too…"

7.0
/10
14 OCT
10
Muse Wonder M
Muse Wonder
AI Models 67 sources · 60-89%

"Meta's frontier agentic LLM: users praise unmatched sub value, but report judgment lapses, web-agent breakage, and a …"

7.0
/10
13 OCT
11
Claude Haiku 5.5 C
Claude Haiku 5.5
AI Models 41 sources · <60%

"Anthropic's speed-tier LLM delivers near-Opus results at low sub-100K cost, but a 5x price jump above 100K tokens and…"

8.6
/10
8 OCT
12
Mistral Large 4 M
Mistral Large 4
AI Models 28 sources · <60%

"Mistral's ~1T-param European frontier model: reportedly near Kimi K3 class on modest compute, but hands-on user data …"

6.0
/10
7 OCT
13
Claude Haiku 4.5 C
Claude Haiku 4.5
AI Models 48 sources · 60-89%

"Anthropic's small model wins technical users on speed and precise code edits, but reviewers split sharply on whether …"

6.5
/10
6 OCT
14
eu/jev e
eu/jev
AI Models 24 sources · <60%

"First System One model hosted in the EU on Hetzner GPUs; users cite strong accuracy, but free self-hosted rival Laya …"

5.0
/10
3 OCT
15
Switchyard S
Switchyard
AI Models 49 sources · 60-89%

"NVIDIA's experimental open-source LLM router for mid-session model switching; HN users validate the cache economics b…"

3.0
/10
3 OCT
16
Claude Sonnet 4.6 C
Claude Sonnet 4.6
AI Models 89 sources · 90%+

"Hands-on dev evals show major agentic autonomy gains, but users flag outages, token bloat, and rivals catching up fast."

7.8
/10
2 OCT
17
JevGPT J
JevGPT
AI Models 30 sources · <60%

"TypeSafe AI's 'System One' model returns typed multiple-choice answers in 70–500ms at $0.042/M input tokens. Cheap, f…"

5.0
/10
1 OCT
18
GPT-6.1 Sol G
GPT-6.1 Sol
AI Models 70 sources · 60-89%

"OpenAI's budget LLM delivers near-Astra results at a fifth of the cost, but users call the GPT-6 lineage underwhelmin…"

6.4
/10
1 OCT
19
Claude Sonnet 5.5 C
Claude Sonnet 5.5
AI Models 39 sources · <60%

"Anthropic's fast mid-tier LLM: ~90% of Opus 5.5 capability at half the price, but power users dispute its token effic…"

8.0
/10
29 SEP
20
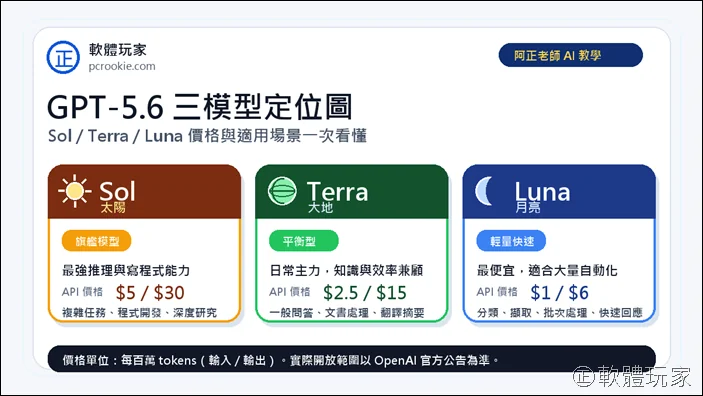
GPT-6 Sol & Luna G
GPT-6 Sol & Luna
AI Models 67 sources · <60%

"OpenAI's cheaper GPT-6 pair wins on cost and metering transparency, but naming confusion and a disputed DeepSWE regre…"

7.5
/10
27 SEP