REVIEWS / AI MODELS / JEVGPT UPDATED OCT 1, 2026 · 33 SOURCES

THE PRODUCT

JevGPT

JevGPT

TypeSafe AI's 'System One' model returns typed multiple-choice answers in 70–500ms at $0.042/M input tokens. Cheap, fast — but a classifier, not a chatbot.

AI MODELS LOW CONFIDENCE

THE VERDICT

5.0

REALITY SCORE · OUT OF 10 · CONFIDENCE LOW

COMPOSED FROM

USERS 7.0 · 30 voices · 100%
CRITICS no published scores yet

SENTIMENT · 33 REVIEWS

+ 30% positive · 55% neutral − 15% negative

OUR VERDICT

WE DON'T RECOMMEND THIS
Score 5.0/10 — no affiliate link by editorial policy
See alternatives →

// Honest verdicts are the whole point. We only monetise products we'd actually recommend.

●29 YOUTUBE ●1 PRODUCTHUNT
USER● n=33
VIDEO● n=3
BRAND● AVAILABLE
INTERNET● n=0

AT A GLANCE · QUOTABLE

  • Rating: 5.0 / 10 (low confidence)
  • User voices: 33 across 2 platforms
  • Sentiment: 30% positive · 15% negative
  • Updated: Oct 1, 2026

GYIBB rates the JevGPT 5.0/10 based on 33 user voices from 2 platforms. Confidence: low. Source: https://gyibb.com/ai-models/jevgpt

⚠ LIMITED DATA Limited data: 4 comments, 29 videos. Consider as preliminary assessment.

BUY IF

Extreme API economics: $0.042 per 1M input tokens, output tokens free (confirmed across user TL;DR and video cost test)

  • + Fast: typed answers in 70–500ms with parallel questions per call
  • + Structured native outputs (Choice ≤255 options, Score, Noul probability) — no fragile output parsing
  • + Real independent test: 9 developer tasks completed for ~$1.05 total (Marvijo video)

SKIP IF

Not a chat model: text-only, 64k tokens/request, 1,200 req/min, 250k tokens/s caps — narrow utility

  • − Cost/speed claims never benchmarked against the right baseline (Gemini 2.5 Flash-Lite) per user pushback
  • − Free open-source alternative 'Laya' allegedly predates and beats it in some cases
  • − All cost figures are list-price estimates, not verified invoices (video's own admission)

Where the layers disagree ⚡

7 CONTRADICTIONS DETECTED

USER data describes Jev as a non-chat decision engine that 'never writes a sentence,' while VIDEO titles ('NEW BEAST Model,' 'GPT-6.1 Sol vs Opus 5.5') frame it as a frontier-LLM rival — positioning inflation between community reality and influencer framing.

VIDEO VS USER

VIDEO (Marvijo) claims ~$1.05 total for 9 dev tests, which ALIGNS with USER-sourced specs ($0.042/M input, free output) — but both layers admit figures are list-price estimates, not verified invoices, and BRAND layer is empty so nothing is officially confirmed.

BRAND VS VIDEO

USER commenters dispute the comparison baseline VIDEOs use: 'Jev vs astra?? Bro is hallucinating' and 'Compare cost with Gemini 2.5 Flash-Lite' — cost-superiority claims were never tested against the cheapest incumbent.

BRAND VS USER

USER layer cites free open-source 'Laya' ('was Jev before Jev... out performs Jev in some cases'), an alternative no VIDEO layer acknowledges.

VIDEO VS USER

USER sentiment splits between enthusiasts running real integrations (OpenRouter router, Hermes skill, coding-harness circuit breakers) and skeptics calling it 'a fancy classifier' — evidence of a real but narrow niche.

USER VS BRAND

A USER-identified existential risk — frontier models stripping layers to offer cheap 'decision' tiers — goes unaddressed because BRAND layer is empty.

BRAND VS USER

PRODUCT identity itself is ambiguous across layers: users call it 'Jev'/'JevGPT'/'JEV,' video mentions 'Jev 1.13,' and the PH comment distinguishes Jev (the model) from JevGPT (the sentence-writing wrapper).

VIDEO VS USER

Value depends on how you pay ⚖

SAME MODEL · TWO BUYERS

ON A SUBSCRIPTION

5.0

Claude Max · ChatGPT Plus · GLM Coding — flat rate, tokens don't bill

No flat-rate plan is evidenced anywhere in the data — Jev is purely per-token priced. As a subscription-style daily assistant it is the wrong shape of tool: a decision/classification engine that natively 'never writes a sentence.' Verdict: low value for Claude Max/ChatGPT Plus-type buyers; the data contains essentially zero subscriber-type users.

ON PER-TOKEN API

8.0

Enterprise / pay-per-use — $/1M, latency, token efficiency bite

The standout use case: $0.042/1M input tokens, free output, 70–500ms typed answers, parallel questions. One real dev test ran 9 tasks for ~$1.05. Best fit is high-volume routing, gating, classification, and circuit-breaking in agent pipelines — exactly how early adopters use it. Caveats: text-only, 64k/request cap, benchmark baselines disputed, free open-source 'Laya' competitor, and figures are l

WHERE THEY AGREE +

+ Extreme API economics: $0.042 per 1M input tokens, output tokens free (confirmed across user TL;DR and video cost test)
+ Fast: typed answers in 70–500ms with parallel questions per call
+ Structured native outputs (Choice ≤255 options, Score, Noul probability) — no fragile output parsing
+ Real independent test: 9 developer tasks completed for ~$1.05 total (Marvijo video)
+ Genuine early integrations: OpenRouter router for cheap-model dispatch, Hermes skill, coding-harness circuit breakers

WHERE THEY DON'T −

− Not a chat model: text-only, 64k tokens/request, 1,200 req/min, 250k tokens/s caps — narrow utility
− Cost/speed claims never benchmarked against the right baseline (Gemini 2.5 Flash-Lite) per user pushback
− Free open-source alternative 'Laya' allegedly predates and beats it in some cases
− All cost figures are list-price estimates, not verified invoices (video's own admission)
− Moat risk: users openly note frontier models could add cheap 'decision' tiers and obsolete it

Where the 33 sources came from

VIEW EVERY CITATION →
YOUTUBE
29
PRODUCTHUNT
1

The four realities of the JevGPT

Most review sites collapse everything into one number. We keep the layers separate so you can see where reality bends.

01
USER
n=33 · 2 platforms

What actual buyers say

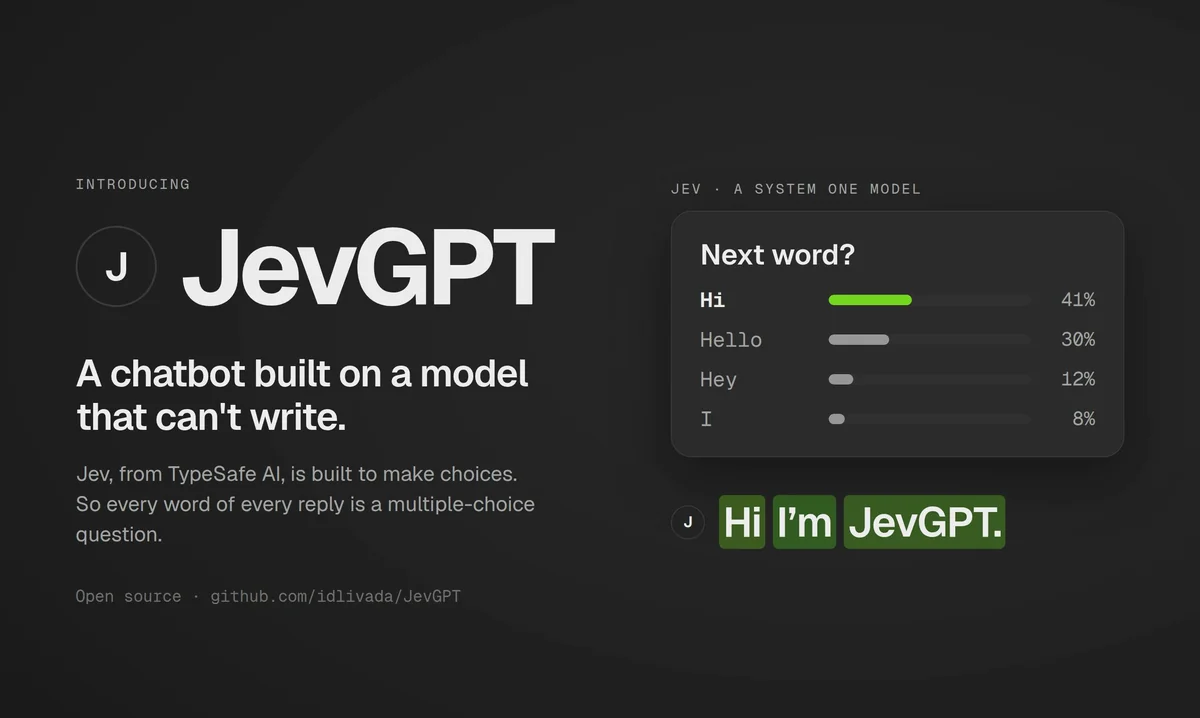
USER comments reveal a technically engaged, API-developer-skewed audience. The Product Hunt launch comment (from the maker) frames Jev as a 'System One' decision model: input a situation plus a list of options, get a probability per option in milliseconds; it 'never writes a sentence' natively — JevGPT is the wrapper that forces sentence output by picking each next word from a 1,772-word vocabulary as chained multiple-choice questions. A highly upvoted community TL;DR confirms specs: typed answers (Choice up to 255 options, Score on a user-defined scale, Noul = probability a statement is true), parallel questions in one call, 70–500ms responses, $0.042 per 1M input tokens with output free, and hard limits (250k tokens/s, 1,200 req/min, 64k tokens/request, text only). Real adoption exists: one user wired JEV into Hermes via OpenRouter as a 'front door' to a DeepSeek coding harness ('Surgical Scoping, Deterministic Circuit Breakers, Objective Quality Checks, Speed & Hygiene'); others ask about using it as a Codex router to cheaper models, handling 100-option dependent dropdowns, trading-model development, and slop detection. Pushback is substantive: 'It's text to classes model. Basically a fancy classifier. Still cool tho'; claims that comparisons vs Astra are the wrong baseline ('Compare cost with Gemini 2.5 Flash-Lite'); assertions that open-source 'Laya' 'was Jev before Jev... and out performs Jev in some cases'; and a stated moat concern that frontier models offering cheaper decision tiers 'could jeopardize Jev's utility.' One commenter insists hallucination and non-determinism are the real issues, to which the video author conceded Jev's use case differs from GPT.
02
VIDEO
n=29 · YouTube

What reviewers showed on camera

Three YouTube videos, all very recent. (1) Jack Roberts (279k subs, ~82.9k views) 'Jev AI Just Dropped, And.…' — the major amplification event; his comment section became the de facto community forum, hosting the integration stories and the classifier-vs-chat debate. (2) AI with Surya (24.7k subs, ~18.2k views) 'JEV AI is the NEW BEAST Model with Speed and Cost' — speed/cost framing; viewers requested side-by-side comparison tables (cost/request, speed, accuracy) to make claims concrete, questioned whether it's 'just' a cheap classifier, while conceding Jev 'nailed' the cost-speed-precision tradeoff on the decision side. (3) Marvijo AI Software (4.6k subs, 205 views) 'JEV: GPT-6.1 Sol vs Opus 5.5 | 9 Real Dev Tests' — the only hands-on benchmark in the data: Jev used alongside GPT-6.1 Sol and Claude Opus 5.5 across 9 developer tasks, total Jev cost ~$1.05 ($0.59 Opus-equivalent + $0.46 GPT-equivalent + $0.002 probes) — but the channel itself caveats these are 'Jev list-price estimates, not verified invoices,' and a browser-access fault was included in cost but excluded from ratings. Confirms Jev 1.13 at $0.042/M input, free output.

Jev AI Just Dropped, And.…

Jack Roberts · 82,930 views

"[comment] 📈Unlock my Jarvis (Plus Astra FULL course): https://bit.ly/4kol0y5 🚨Connect Jev to ANYTHING: https://bit.ly/46ybfHH [comment] Even if AI progress stopped today, there’s still tons of potential in how all these amazing tools can be…"

JEV AI is the NEW BEAST Model with Speed and Cost

AI with Surya · 18,211 views

"[comment] : When comparing Jev AI against other models, showing a side-by-side static comparison table on screen (e.g., cost per request, speed, and accuracy metrics) would make the performance benefits more concrete for the viewer. [commen…"

JEV: GPT-6.1 Sol vs Opus 5.5 | 9 Real Dev Tests

Marvijo AI Software · 205 views

"[comment] which tool would you trust with these developer jobs? which result surprised you most? the separate cost comment lists the Jev usage and its limits. [comment] Jev costs across the complete test: Claude Opus 5.5 High: $0.591705450 …"

03
INTERNET
n=0 · review sites

What the press said

No aggregate ratings were found for this product during the last harvest.
04
BRAND
official source

What the brand says

no brand page found

The official brand page was not successfully scraped during the last harvest.
Visit Official Site →

SIMILAR IN THIS CATEGORY

See all →
Gemini 3

Gemini 3

8.8

✓ Top-tier benchmark performance (beats GPT-5.1, Sonnet 4.5 on TvP and ARC-AGI)

DeepSeek R1

DeepSeek R1

8.8

✓ Superior performance on math and coding benchmarks (MATH-500, Codeforces)

Gemini 3.6 Flash Family

Gemini 3.6 Flash Family

8.8

✓ Exceptional multimodal capabilities (audio, images, interactive elements)

Claude Haiku 5.5

Claude Haiku 5.5

8.6

✓ Fastest model in class per multiple benchmark runs

DATA SOURCES & AUDIT

29
YOUTUBE
1
PRODUCTHUNT
3
YOUTUBE VIDEOS

33 data points across 2 platforms, synthesized via GYIBB's Truth Engine and fact-checked against source data before publication.

CONFIDENCE: LOW · ANALYSED: OCTOBER 1, 2026 AT 07:41 PM · PROMPT V1.0 · READ METHODOLOGY →

Was this review helpful?

Embed this review
Writing about JevGPT? Add the GYIBB verdict — free, no account needed.

<a href="https://gyibb.com/ai-models/jevgpt" target="_blank" rel="noopener">
  <img src="https://gyibb.com/badge/ai-models/jevgpt.svg" alt="GYIBB rating for JevGPT" width="220" height="56">
</a>
← Back to all reviews

JevGPT

GYIBB SCORE: 5.0/10

See alternatives →



