REVIEWS / AI MODELS / GPT-6 SOL & LUNA UPDATED SEP 27, 2026 · 70 SOURCES

THE PRODUCT

GPT-6 Sol & Luna

GPT-6 Sol & Luna

OpenAI's cheaper GPT-6 pair wins on cost and metering transparency, but naming confusion and a disputed DeepSWE regression cloud the verdict.

AI MODELS LOW CONFIDENCE

THE VERDICT

7.5

REALITY SCORE · OUT OF 10 · CONFIDENCE LOW

COMPOSED FROM

USERS 5.5 · 67 voices · 100%
CRITICS no published scores yet

SENTIMENT · 70 REVIEWS

+ 0% positive · 100% neutral − 0% negative
●51 YOUTUBE ●15 HN ●1 PRODUCTHUNT
USER● n=70
VIDEO● n=3
BRAND● AVAILABLE
INTERNET● n=0

AT A GLANCE · QUOTABLE

  • Rating: 7.5 / 10 (low confidence)
  • User voices: 70 across 3 platforms
  • Sentiment: 0% positive · 0% negative
  • Updated: Sep 27, 2026

GYIBB rates the GPT-6 Sol & Luna 7.5/10 based on 70 user voices from 3 platforms. Confidence: low. Source: https://gyibb.com/ai-models/gpt-6-sol-luna

⚠ LIMITED DATA Limited data: 19 comments, 51 videos. Consider as preliminary assessment.

BUY IF

Strong cost story: relayed ~9% of Opus 5's cost on Automation Bench, ~80% below Fable 5.1 on DeepSWE, '50% cheaper' video framing

  • + Metering transparency praised: 'Pro 20x = 4 * Pro 5x = 20 * Plus, exactly as advertised,' no separate meters or 5h-limit games
  • + See user reviews

SKIP IF

Limited data available

  • − Limited data available
  • − Limited data available

Where the layers disagree ⚡

6 CONTRADICTIONS DETECTED

USER vs VIDEO on naming: HackerNews says the Sol/Luna/Terra/Astra names 'don't communicate anything meaningful,' while a YouTube commenter calls OpenAI 'much clearer in its differentiation between the models' — directly opposite reads of the same taxonomy.

VIDEO VS USER

USER (ProductHunt relay) claims 'matches Claude Fable 5.1 on DeepSWE at ~80% lower cost,' but a VIDEO commenter counters: 'In DeepSWE 5.6 Sol is beating 6 Sol... feels like 6 Sol is actually 6 Terra, just renamed' — a claimed regression the missing INTERNET layer can't arbitrate.

BRAND VS VIDEO

USER vs USER on plan value: one commenter 'statistically verified' OpenAI Pro 20x = 4× Pro 5x with no separate meters, while another argues 'since around July... Anthropic is actually giving more on $200' in raw API costs.

USER VS BRAND

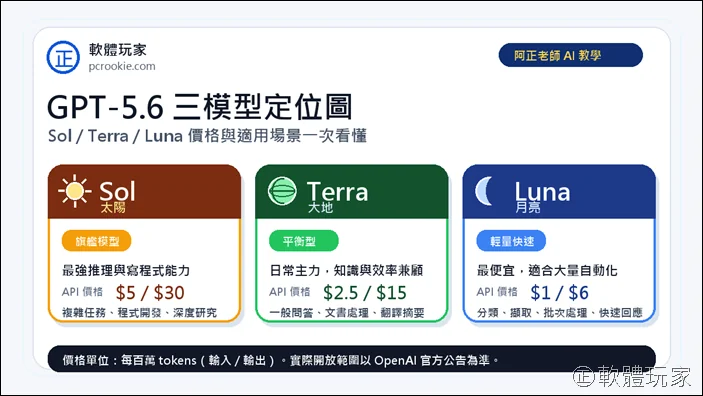
ALIGNMENT on Luna's price: the VIDEO '50% CHEAPER' framing, 'Luna 6 Max is very hard to beat at that price,' and 'hours of looped use ≈ 4% of weekly usage' match the USER framing of cheap models as workhorses for explicit, well-specified tasks.

VIDEO VS USER

One USER reads Luna's low price as 'suppressing inexpensive Chinese model competition' (strategy), while VIDEO users celebrate the same price as a consumer win — same fact, opposite interpretations.

VIDEO VS USER

USER benchmark skepticism ('I only trust what a model does with MY code') sits against both the relayed brand-style claims and creator framing that lean on Automation Bench / DeepSWE / FrontierCode numbers.

BRAND VS VIDEO

Value depends on how you pay ⚖

SAME MODEL · TWO BUYERS

ON A SUBSCRIPTION

7.5

Claude Max · ChatGPT Plus · GLM Coding — flat rate, tokens don't bill

Sol reportedly matches Claude Fable 5.1 xhigh on merge-ready coding tasks, and users say mid-tier models now cover most daily work — one happily awaits 6 Luna Max. Flat-rate OpenAI plans earn praise for unmetered usage with no separate meters, though some argue Anthropic's $200 tier now delivers more, and constant naming churn confuses even loyal users.

ON PER-TOKEN API

8.5

Enterprise / pay-per-use — $/1M, latency, token efficiency bite

Cost-efficiency is the headline: Sol beats Claude Opus 5 on Automation Bench at roughly 9% of cost per task and matches Fable 5.1 on DeepSWE at about 80% lower cost. OpenAI's relative transparency helps, but benchmark skepticism and prior Sol-line instruction quirks (under/over-engineering modes) temper enthusiasm slightly. Per-token value still looks exceptional.

WHERE THEY AGREE +

+ Strong cost story: relayed ~9% of Opus 5's cost on Automation Bench, ~80% below Fable 5.1 on DeepSWE, '50% cheaper' video framing
+ Metering transparency praised: 'Pro 20x = 4 * Pro 5x = 20 * Plus, exactly as advertised,' no separate meters or 5h-limit games
+ See user reviews

WHERE THEY DON'T −

− Limited data available

Where the 70 sources came from

VIEW EVERY CITATION →
YOUTUBE
51
HN
15
PRODUCTHUNT
1

The four realities of the GPT-6 Sol & Luna

Most review sites collapse everything into one number. We keep the layers separate so you can see where reality bends.

01
USER
n=70 · 3 platforms

What actual buyers say

HackerNews discussion (top-voted comments) centers on four themes. (1) Naming confusion: 'what the hell do Terra, Sol, and Astra really mean? Which one of them is the effective successor to gpt-5.4-mini?' — tier names read as marketing, not signal. (2) Practical tiering: one user compares model sizes to delegating chores — smaller models (Nano/Luna-class) 'won't reliably handle complex open-ended tasks' and need 'very explicit instruction,' so cheap models only pay off when the decision tree is clear. A 5.6 Sol user reports a reasoning 'dead zone': medium 'under engineered and took short cuts,' high 'over engineered and ignored instructions.' (3) Plan economics: OpenAI's metering gets rare praise — 'statistically verified that OpenAI Pro 20x = 4 * Pro 5x = 20 * Plus, exactly as advertised,' with no Anthropic-style separate meter ('five Fable sessions per week') — but a rebuttal claims 'since around July... Anthropic is actually giving more on $200' measured in raw API costs, and local-model alternatives require $6k–12k hardware (Mac Ultra 5, dual DGX Sparks). (4) Benchmark posture: users appreciate that the announcement admits GPT-6 Sol only *matches* Claude Fable 5.1 xhigh on FrontierCode at lower cost (a sign of 'skilled engineers' who 'recognize slop'), yet others distrust benchmarks outright: 'I only trust what a model does with MY code.' Additional friction: one commenter frames Luna's pricing as 'about suppressing inexpensive Chinese model competition.' A ProductHunt comment relays the official pitch: Sol 'beats Claude Opus 5 on Automation Bench at roughly 9% of the cost per task' and matches Fable 5.1 on DeepSWE at ~80% lower cost, carrying over Astra's alignment gains including 'fewer misleading claims about their own coding work.' Company-ethics sentiment is mixed (copyright training data, differential-privacy debate), but several users say delivered value 'far outweighed' the concerns.
02
VIDEO
n=51 · YouTube

What reviewers showed on camera

Three videos, 14.6k–638k subs — note the excerpts are viewer comment sections, not creator verdicts. Chase AI's 'GPT 6 Sol & Luna Are Here (And 50% CHEAPER!)' draws hype ('Anthropic and OpenAI moving like Ronaldo and Messi prime') plus one viewer glad OpenAI is 'much clearer in its differentiation between the models (Luna, Terra and Sol),' while another mourns 'rip terra.' Matthew Berman's video surfaces the most substantive signal: 'In DeepSWE 5.6 Sol is beating 6 Sol, it feels like 6 Sol is actually 6 Terra, just renamed to Sol' — a possible regression/rebrand concern — set against cost enthusiasm ('using Luna for hours today, in a loop, and it's only used about 4% of my weekly usage'), workflow adoption ('GPT-6 Sol + Sewkal Pro will be my research writing workflow'), and free-reset praise. AI Coding Daily's 144-coding-prompt test prompts: 'Luna 6 Max is very hard to beat at that price,' tier-mapping confusion ('GPT 6 - Astra ( GPT 6 Sol ) ; GPT 6 SOL ( GPT 6 Terra )'), conditional praise ('Luna High... if you provide enough context and focused prompts, it handles most things well'), and one defector noting 'Opus 5.5 is an absolute beast' used to orchestrate GPT models.

GPT 6 Sol & Luna Are Here (And 50% CHEAPER!)

Chase AI · 65,691 views

"[comment] Get my Claude Code + Codex Masterclass 👉 https://www.skool.com/chase-ai [comment] Anthropic and OpenAI moving like Ronaldo and Messi prime [comment] Grok 4.7 being worse than Luna is such a joke [comment] We’re in the end game now…"

GPT-6 Sol and Luna Are HERE!

Matthew Berman · 59,882 views

"[comment] I've been using Luna for hours today, in a loop, and it's only used about 4% of my weekly usage. [comment] In DeepSWE 5.6 Sol is beating 6 Sol, it feels like 6 Sol is actually 6 Terra, just renamed to Sol. [comment] GPT-6 Sol + Se…"

I Tested NEW GPT-6-Sol and GPT-6-Luna on 144 Coding Prompts

AI Coding Daily · 18,931 views

"[comment] Luna 6 Max is very hard to beat at that price. [comment] GPT 6 - Astra ( GPT 6 Sol ) ; GPT 6 SOL ( GPT 6 Terra ) [comment] now we wait for google to release AGI with Gemini 4 pro next decade. Also since anthropic called opus 5.5 f…"

03
INTERNET
n=0 · review sites

What the press said

No aggregate ratings were found for this product during the last harvest.
04
BRAND
official source

What the brand says

no brand page found

The official brand page was not successfully scraped during the last harvest.
Try Official site →

* This page may contain affiliate links. No additional cost to you.

SIMILAR IN THIS CATEGORY

See all →


Gemini 3

Gemini 3

8.8

✓ Top-tier benchmark performance (beats GPT-5.1, Sonnet 4.5 on TvP and ARC-AGI)

DeepSeek R1

DeepSeek R1

8.8

✓ Superior performance on math and coding benchmarks (MATH-500, Codeforces)

Gemini 3.6 Flash Family

Gemini 3.6 Flash Family

8.8

✓ Exceptional multimodal capabilities (audio, images, interactive elements)

Claude Haiku 5.5

Claude Haiku 5.5

8.6

✓ Fastest model in class per multiple benchmark runs

DATA SOURCES & AUDIT

51
YOUTUBE
15
HN
1
PRODUCTHUNT
3
YOUTUBE VIDEOS

70 data points across 3 platforms, synthesized via GYIBB's Truth Engine and fact-checked against source data before publication.

CONFIDENCE: LOW · ANALYSED: SEPTEMBER 27, 2026 AT 11:09 AM · PROMPT V1.0 · READ METHODOLOGY →

Was this review helpful?

Embed this review
Writing about GPT-6 Sol & Luna? Add the GYIBB verdict — free, no account needed.

<a href="https://gyibb.com/ai-models/gpt-6-sol-luna" target="_blank" rel="noopener">
  <img src="https://gyibb.com/badge/ai-models/gpt-6-sol-luna.svg" alt="GYIBB rating for GPT-6 Sol & Luna" width="220" height="56">
</a>
← Back to all reviews

GPT-6 Sol & Luna

GYIBB SCORE: 7.5/10

Visit →

