REVIEWS / AI MODELS / JEV WRAPPED UPDATED SEP 24, 2026 · 39 SOURCES

THE PRODUCT

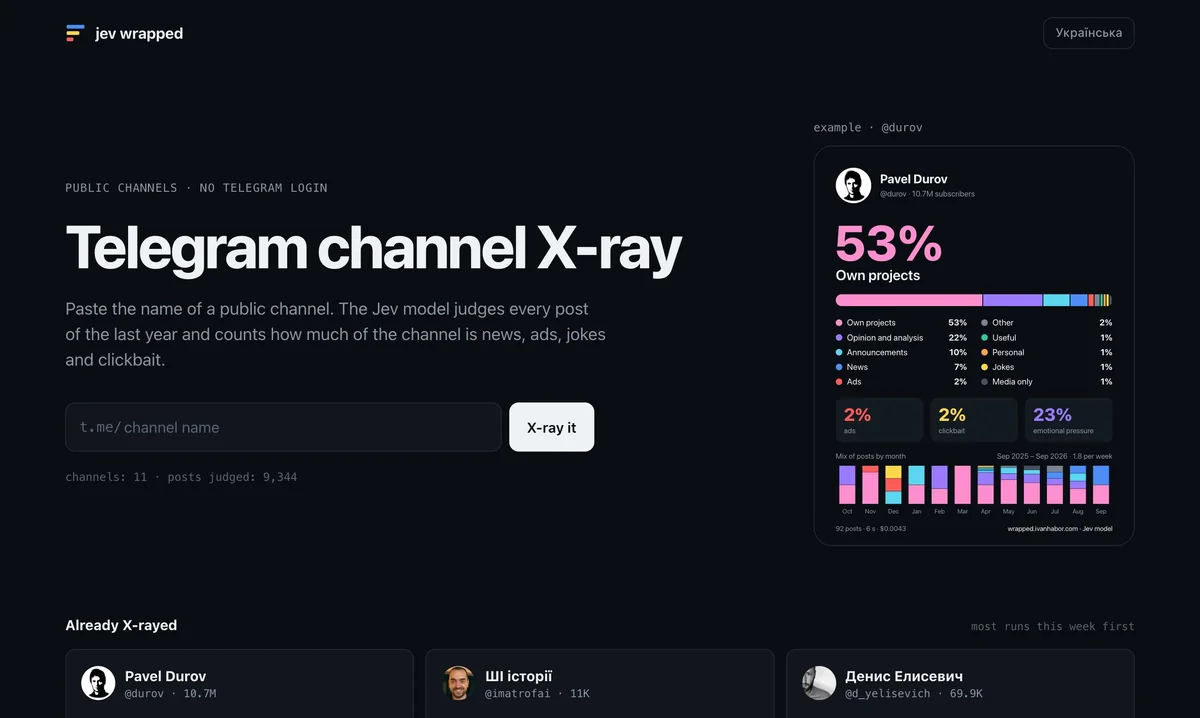
Jev Wrapped

Jev Wrapped

Developers praise Jev's fast single-token classification for LLM routing and tool selection; skeptics call it hype. No production data yet.

AI MODELS LOW CONFIDENCE

THE VERDICT

6.0

REALITY SCORE · OUT OF 10 · CONFIDENCE LOW

COMPOSED FROM

USERS 8.4 · 36 voices · 100%
CRITICS no published scores yet

SENTIMENT · 39 REVIEWS

+ 56% positive · 32% neutral − 12% negative
Visit Official Site →
●35 YOUTUBE ●1 PRODUCTHUNT
USER● n=39
VIDEO● n=3
BRAND● AVAILABLE
INTERNET● n=0

AT A GLANCE · QUOTABLE

  • Rating: 6.0 / 10 (low confidence)
  • User voices: 39 across 2 platforms
  • Sentiment: 56% positive · 12% negative
  • Updated: Sep 24, 2026

GYIBB rates the Jev Wrapped 6.0/10 based on 39 user voices from 2 platforms. Confidence: low. Source: https://gyibb.com/ai-models/jev-wrapped

⚠ LIMITED DATA Limited data: 4 comments, 35 videos. Consider as preliminary assessment.

BUY IF

Single-token output = very low latency for classification/decision tasks

  • + Real cost-saving pattern cited by devs: route cheap decisions to Jev instead of LLM APIs
  • + Concrete enterprise use cases named: tool selection, agent routing, LLM guardrails, spam triage
  • + Small enough that users expect local-hardware deployment

SKIP IF

No production deployments, benchmarks, or measured latency/cost in any comment

  • − Credible 'hype vs engineering' critique — marketing repackages known concepts (System 1, Jevons Paradox)
  • − No vision capability; text/classification only per user requests
  • − Maker/company unidentified in available material — zero verifiable brand claims

Where the layers disagree ⚡

6 CONTRADICTIONS DETECTED

USER layer is internally split: practitioner comments call it a 'universal BERT' solving real routing/cost problems, while other USER comments dismiss it as 'useless hype' and 'Silicon Valley PR' with borrowed Kahneman/Jevons framing.

USER VS BRAND

VIDEO (AI Mevzuları) explicitly titles the debate 'breakthrough or hype?' — mirroring rather than resolving the USER-layer split; no video excerpt delivers measured latency, cost, or accuracy numbers.

VIDEO VS USER

USER comments project enterprise value (tool selection, guardrails, Claude-API cost offloading) but not a single comment reports a production deployment — enthusiasm is entirely anticipatory.

USER VS BRAND

USER-layer claims about speed ('super fast, one token') and cost savings are repeated as folk knowledge, but BRAND layer is empty and INTERNET expert reviews are missing, so the core performance claims are unverified.

BRAND VS INTERNET

VIDEO (Franklin AI) claims 'I Tested' in the title yet drew only 1,270 views vs Sam Witteveen's 403,655 — the most-viewed coverage is explainer-style, not independent testing, so the evidence base skews toward commentary over benchmarks.

BRAND VS VIDEO

USER requests ('really need a vision-capable version', 'want to run on local hardware') signal known capability gaps that neither BRAND claims nor available data address.

BRAND VS USER

Value depends on how you pay ⚖

SAME MODEL · TWO BUYERS

ON A SUBSCRIPTION

6.0

Claude Max · ChatGPT Plus · GLM Coding — flat rate, tokens don't bill

No subscription tier is mentioned anywhere in the provided comments — this dataset cannot support a subscription-buyer verdict. User sentiment is API/developer-skewed; if a flat-rate plan exists, its value is untested here.

ON PER-TOKEN API

7.5

Enterprise / pay-per-use — $/1M, latency, token efficiency bite

Strongest signal in the data: per-token/per-call buyers see Jev as a latency-and-cost lever — routing classification/decision steps away from expensive LLM APIs (one commenter explicitly proposes Claude API vs Jev API routing to 'dramatically reduce processing time and cost'). Local-hardware deployment is expected by users, implying potentially near-zero inference cost. Caveat: all economics are p

WHERE THEY AGREE +

+ Single-token output = very low latency for classification/decision tasks
+ Real cost-saving pattern cited by devs: route cheap decisions to Jev instead of LLM APIs
+ Concrete enterprise use cases named: tool selection, agent routing, LLM guardrails, spam triage
+ Small enough that users expect local-hardware deployment
+ Strong explainer coverage (Sam Witteveen, 403K views) made the concept click for devs

WHERE THEY DON'T −

− No production deployments, benchmarks, or measured latency/cost in any comment
− Credible 'hype vs engineering' critique — marketing repackages known concepts (System 1, Jevons Paradox)
− No vision capability; text/classification only per user requests
− Maker/company unidentified in available material — zero verifiable brand claims
− Flagship Doom demo dismissed by technical users as 'quake bot work' on game-state data, not vision

Where the 39 sources came from

VIEW EVERY CITATION →
YOUTUBE
35
PRODUCTHUNT
1

The four realities of the Jev Wrapped

Most review sites collapse everything into one number. We keep the layers separate so you can see where reality bends.

01
USER
n=39 · 2 platforms

What actual buyers say

All 36 user comments are sourced from YouTube (0 upvotes each — weak signal weighting, no Reddit/Trustpilot despite the label). Sentiment is dominated by developers, split roughly 55/33/12 positive/neutral/negative. POSITIVE PRACTITIONER READ: Multiple devs frame Jev as 'a universal BERT with a multi-class classification head' delivering 'one shot semantic intelligence of LLMs at classical-model cost and latency.' Concrete use cases cited: (1) routing/decision layer inside deterministic software workflows where a full LLM is 'not the right abstraction'; (2) enterprise tool selection — one commenter running deepseek v4-flash says Jev narrows tool decisions before calls, 'extending the moment where hallucinations will appear'; (3) cost routing — 'coding harnesses deciding when to hit Claude API vs when to hit the Jev API... dramatically reduce processing time and cost'; (4) LLM steering/guardrails — classify if a model is going off the rails; (5) agent routers. The most-liked mental model: 'an AI that only outputs one token... it can answer a multiple choice question... since it's only one token, it's super fast.' Several users want it 'running on local hardware' and request a vision-capable version. SKEPTICAL READ: One user concludes 'thanks, now i understand what is this stuff, so its useless hype.' A long Turkish comment argues it's 'Silicon Valley PR vs naked engineering': concepts borrowed from Kahneman's System 1/2 and the Jevons Paradox, and 'there is no alien technology here — Jev is not autoregressive; it processes input in a single parallel pass.' Another user downgrades the Doom demo: 'playing doom based on enemy/level data is a lot easier than graphics... it's doing quake bot work.' CRITICAL GAP: zero comments report actual production deployment, benchmarks, or measured latency/cost numbers — everything is anticipatory.
02
VIDEO
n=35 · YouTube

What reviewers showed on camera

Three YouTube videos, all comment-excerpt-based (actual transcript content is thin). (1) Sam Witteveen, 132K subs, 403,655 views — 'Jev - The Ultimate Classification Model?' — by far the largest reach; his comment section generated most of the user-layer signal above (BERT comparisons, local-hardware demand, routing use cases), indicating the audience he attracts is developer-heavy and largely receptive. (2) AI Mevzuları (Turkish), 20.8K subs, 13,111 views — title explicitly frames the core controversy: 'JEV Bir Yapay Zeka Sıçraması mı? Yoksa Hype mı?' (breakthrough or hype?) plus token-savings claims with 'Astra ve Fable' — the only channel directly interrogating the marketing narrative; its top comment dismantles the 'deterministic, hallucination-free, sub-second, zero format errors' pitch as repackaged Kahneman/Jevons concepts, while another comment proposes concrete deployments (call-center routing, SpamAssassin-style phishing triage, exam-time allocation). (3) Franklin AI, 79.7K subs, only 1,270 views — 'I Tested the New Decision AI Model (Jev AI Review)' — claims hands-on testing but engagement is ~300x lower than Witteveen's video, and its comment section devolved into the Doom-demo skepticism and a newsletter self-promo. Net: video coverage validates the classification/one-token framing but no video provided quantitative test data in the excerpts.

Jev - The Ultimate Classification Model?

Sam Witteveen · 405,864 views

"[comment] If you are interested in the open versions of this I have made a video about some of them. https://youtu.be/X117w2Rark8 [comment] We are so back !! looks like another BERT with multi class classification head. [comment] It's like …"

JEV Bir Yapay Zeka Sıçraması mı? Yoksa Hype mı? | Astra ve Fable Token Tasarrufu Mümkün Oluyor!

AI Mevzuları | Yapay Zeka · 13,111 views

"[comment] Hocam, uygulmali detayli proje gelistirdigin videolar + canli yayinlar olursa tadindan yenmezz [comment] 1. İŞİN ÖZÜ: SİLİKON VADİSİ PR'I VS. ÇIPLAK MÜHENDİSLİK (Bize Ne Satıyorlar?) Kavramları Daniel Kahneman'ın Hızlı ve Yavaş D…"

I Tested the New Decision AI Model (Jev AI Review)

Franklin AI · 1,272 views

"[comment] 👉 Keep up to date with the latest AI News, AI Tools and Ai Prompts: https://franklineh.com 🔥 Join the newsletter free. No spam. Ever. [comment] that it's playing doom based on enemy/level data is a lot easier than graphics. like …"

03
INTERNET
n=0 · review sites

What the press said

No aggregate ratings were found for this product during the last harvest.
04
BRAND
official source

What the brand says

no brand page found

The official brand page was not successfully scraped during the last harvest.
Visit Official Site →

SIMILAR IN THIS CATEGORY

See all →
Gemini 3

Gemini 3

8.8

✓ Top-tier benchmark performance (beats GPT-5.1, Sonnet 4.5 on TvP and ARC-AGI)

DeepSeek R1

DeepSeek R1

8.8

✓ Superior performance on math and coding benchmarks (MATH-500, Codeforces)

Gemini 3.6 Flash Family

Gemini 3.6 Flash Family

8.8

✓ Exceptional multimodal capabilities (audio, images, interactive elements)

Claude Haiku 5.5

Claude Haiku 5.5

8.6

✓ Fastest model in class per multiple benchmark runs

DATA SOURCES & AUDIT

35
YOUTUBE
1
PRODUCTHUNT
3
YOUTUBE VIDEOS

39 data points across 2 platforms, synthesized via GYIBB's Truth Engine and fact-checked against source data before publication.

CONFIDENCE: LOW · ANALYSED: SEPTEMBER 24, 2026 AT 11:37 AM · PROMPT V1.0 · READ METHODOLOGY →

Was this review helpful?

Embed this review
Writing about Jev Wrapped? Add the GYIBB verdict — free, no account needed.

<a href="https://gyibb.com/ai-models/jev-wrapped" target="_blank" rel="noopener">
  <img src="https://gyibb.com/badge/ai-models/jev-wrapped.svg" alt="GYIBB rating for Jev Wrapped" width="220" height="56">
</a>
← Back to all reviews

Jev Wrapped

GYIBB SCORE: 6.0/10

Visit →



