THE PRODUCT
GLM 5.3 FlashX
Cheap open-weights model praised for agentic coding, but slow per task, censorship refusals, and a grabby ToS temper enthusiasm.
THE VERDICT
REALITY SCORE · OUT OF 10 · CONFIDENCE MEDIUM
COMPOSED FROM
SENTIMENT · 75 REVIEWS
BEST PRICE TODAY
// Affiliate link — score is unaffected.
AT A GLANCE · QUOTABLE
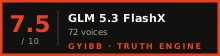
- Rating: 7.5 / 10 (medium confidence)
- User voices: 75 across 3 platforms
- Sentiment: 40% positive · 25% negative
- Updated: Sep 19, 2026
GYIBB rates the GLM 5.3 FlashX 7.5/10 based on 75 user voices from 3 platforms. Confidence: medium. Source: https://gyibb.com/ai-models/glm-5-3-flashx
BUY IF
Beats GPT-5.6-Sol in real user tests per video commenters, not just benchmarks
- + Open weights — runnable locally on high-RAM hardware; 'open weights are a ratchet'
- + Cheap per task: ~$0.05 vs $0.09 (GPT-5.6-Luna), currently 50% subsidized
- + Replaced DeepSeek and GLM 5.2 as default agentic coding model for multiple commenters
SKIP IF
Censorship: refuses Tiananmen Square query in Chinese, same as DeepSeek — 'a nonstarter' for some
- − 7x slower Time-per-Task than Gemini 3.7 Flash / GPT-5.6-Sol; weak for interactive and real-time agentic work
- − Z.ai ToS grants perpetual license over inputs/outputs/name/photo; vague 'national interests' prohibitions
- − Non-English output (Dutch) 'not great' per viewer test
Where the layers disagree ⚡
6 CONTRADICTIONS DETECTEDUSER (HN) measures GLM-5.3-Flash at 7x slower Time-per-Task than Gemini 3.7 Flash/GPT-5.6-Sol and 'not suitable for interactive or agentic work', while VIDEO commenters (Sam Witteveen's audience) use it as their DEFAULT agentic coding model — latency tolerance clearly differs by workload.
VIDEO says '5.3 flash is better than Sol on my tests', but USER comparison counters that a ~5-point intelligence lead over GPT-5.6-Luna is 'meaningless' when speed is 88 vs 130 — real-use praise vs benchmark-style scoring disagree on what matters.
USER layer documents censorship refusals (Tiananmen prompt) and a Z.ai ToS perpetual license over inputs/outputs/name/photo; the VIDEO layer mentions neither issue even once — a striking influencer blind spot.
USER math shows self-hosting yields <$40/month of equivalent API tokens (130M tokens at 50 tps), yet VIDEO commenters still ask about running it on 128GB unified RAM — the privacy/control motive survives the cost argument, likely amplified by the ToS concerns.
USER notes API rates are 50%-subsidized (possibly temporary); VIDEO enthusiasm for cheapness aligns but neither layer knows post-subsidy economics.
VIDEO (Fahd Mirza) reports weak Dutch output while nearly all USER and VIDEO praise is English coding — multilingual quality is essentially unverified.
Value depends on how you pay ⚖
SAME MODEL · TWO BUYERSON A SUBSCRIPTION
7.5Claude Max · ChatGPT Plus · GLM Coding — flat rate, tokens don't bill
For flat-rate plan buyers (e.g., GLM Coding Plan), capability is the draw: commenters made 5.3 Flash their default agentic coder, preferring it over Sol and DeepSeek. But the same community cites 88-vs-130 speed and slower time-per-task, which stings in interactive IDE loops. Caveat: the provided comments skew API-cost-skeptic (HN), so subscription verdicts are inferred, not first-hand.
ON PER-TOKEN API
6.5Enterprise / pay-per-use — $/1M, latency, token efficiency bite
Per-token buyers get the clearest win: ~$0.05/task vs $0.09 (GPT-5.6-Luna), currently 50% subsidized — strong for batch/background agents. But HN's Time-per-Task analysis shows 7x slower than Gemini 3.7 Flash/Sol, hurting real-time workflows and Kafka-style enterprise throughput. The ToS license terms and censorship refusals add enterprise risk, and subsidy permanence is unknown.
WHERE THEY AGREE +
WHERE THEY DON'T −
Where the 75 sources came from
VIEW EVERY CITATION →The four realities of the GLM 5.3 FlashX
Most review sites collapse everything into one number. We keep the layers separate so you can see where reality bends.
What actual buyers say
What reviewers showed on camera
GLM 5.3 Flash vs GLM 5.3: When Cheaper Is the Right Call
Sam Witteveen · 60,357 views
"[comment] I had been using GLM 5.2 as my default agentic coding model, and now I have switched to GLM 5.3 Flash, and I can feel the difference. I'm using frontier models less and less these days. [comment] Screw benchmarks, 5.3 flash is bet…"
Open-Source AI Took Over 3D Again - GLM 5.3 & Qwen 3.8 Max
Stefan 3D AI · 41,297 views
"[comment] 🔹 Try Fish Audio's API / MCP: https://fish.audio/?fpr=stefan3d 🦊 My 3D AI Course: https://learn3d.ai/3d-ai/glm-qwen Learn the complete process of turning AI assets into production-ready 3D characters—from concept to Unreal Engi…"
GLM-5.3-Flash vs Qwen3.8-Flash: I Made Them Flirt, Code, and Fix
Fahd Mirza · 8,690 views
"[comment] 📬Weekly AI Newsletter: https://fahdmirza.substack.com/ ⚡Buy Me a Coffee to support the channel: https://ko-fi.com/fahdmirza 🔥Hi All, Please support the channel by becoming a member at https://www.youtube.com/channel/UCPix8N6PMRI…"
What the press said
What the brand says
no brand page found
* This page may contain affiliate links. No additional cost to you.
SIMILAR IN THIS CATEGORY
See all →



DATA SOURCES & AUDIT
75 data points across 3 platforms, synthesized via GYIBB's Truth Engine and fact-checked against source data before publication.
CONFIDENCE: MEDIUM · ANALYSED: SEPTEMBER 19, 2026 AT 08:38 PM · PROMPT V1.0 · READ METHODOLOGY →
Was this review helpful?
Embed this review