THE PRODUCT
Aider
CLI-based AI coding assistant that edits repos directly via LLMs, git-commits changes, and targets real refactors—not autocomplete.
THE VERDICT
REALITY SCORE · OUT OF 10 · CONFIDENCE LOW
COMPOSED FROM
SENTIMENT · 878 REVIEWS
OUR VERDICT
// Honest verdicts are the whole point. We only monetise products we'd actually recommend.
AT A GLANCE · QUOTABLE
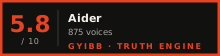
- Rating: 5.8 / 10 (low confidence)
- User voices: 878 across 5 platforms
- Sentiment: 40% positive · 35% negative
- Updated: Aug 10, 2026
GYIBB rates the Aider 5.8/10 based on 878 user voices from 5 platforms. Confidence: low. Source: https://gyibb.com/ai-coding/aider
BUY IF
Git-native workflow: every edit is a commit, instantly reversible
- + Tree-sitter repo map provides broader context than line-level autocomplete
- + Strong for boilerplate, framework migrations, and greenfield scaffolding
- + Model-agnostic: works with OpenAI, Anthropic, DeepSeek, and local LLMs
SKIP IF
LLM back-and-forth unreliable for ambiguous or complex logic tasks
- − API cost can escalate quickly on large-context, multi-file work
- − Output requires careful review—hallucinated APIs and methods are common
- − Effective only when user decomposes tasks like briefing a junior dev
Where the layers disagree ⚡
6 CONTRADICTIONS DETECTEDVIDEO vs USER: Videos frame Aider as a productivity multiplier that eliminates 'getting stuck,' but top-voted USER comments argue LLM back-and-forth for real problem-solving is 'an absolute disaster' and that prompting + review is often slower than manual coding.
VIDEO vs USER: Better Stack cites Aider's self-reported 88% benchmark with no independent verification; USER comments describe partial refactors that 'didn't get fully done' and hallucinated APIs, suggesting real-world success rates are context- and model-dependent.
USER internal split: Users who treat Aider as a 'junior dev' for well-scoped boilerplate tasks report success; users who expect it to handle ambiguous, complex refactors report frustration—outcome is gated by task decomposition skill.
VIDEO omits cost; USER flags it: One USER burned $10 in a single session, and multiple users want local-model support to avoid API costs—videos do not address token economics at all.
USER model-dependency risk: Users document specific cases where Claude 3 Opus 'bombed hard' (invented nonexistent methods) while ChatGPT succeeded, meaning Aider's effective quality is bounded by the underlying LLM choice—videos treat Aider as the unit of value without isolating model variance.
MISSING LAYERS: With no EXPERT reviews or BRAND claims provided, the only performance figures in circulation (88% benchmark) are Aider's own, and there is no independent calibration of capability or reliability.
WHERE THEY AGREE +
WHERE THEY DON'T −
Where the 878 sources came from
VIEW EVERY CITATION →The four realities of the Aider
Most review sites collapse everything into one number. We keep the layers separate so you can see where reality bends.
What actual buyers say
What reviewers showed on camera
Why you should use Aider for AI coding
Zen van Riel · 35,637 views
"one of the top reasons why developers take a long time to complete their work is because they get stuck and then they don't have a great way to get quick help I personally remember desperately scrolling stack Overflow in hopes of findin…"
I Let Aider AI Refactor My App
Better Stack · 12,615 views
"This is Aider, an open-source AI pair programmer that lives in your terminal. And unlike Copilot, it's not autocomplete. It edits your repo directly using a structured file map built with a tree-sitter. It supports over 100 languages, a…"
Aider Review (2025) | Is This AI Tool Worth It?
Skillcraft AI · 641 views
"Hey everyone. In this video, let's talk about Aderai. In order to do so, here we are at Ader. And what is ADER all about? Well, it's AI pair programming in your terminal. Ader lets you pair program with LLMs to start a new project o…"
What the press said
What the brand says
no brand page found
SIMILAR IN THIS CATEGORY
See all →

DATA SOURCES & AUDIT
878 data points across 5 platforms, synthesized via GYIBB's Truth Engine and fact-checked against source data before publication.
CONFIDENCE: LOW · ANALYSED: AUGUST 10, 2026 AT 05:20 AM · PROMPT V1.0 · READ METHODOLOGY →
Was this review helpful?
Embed this review